Recommended resources
The freely available resources this lesson will direct you to.
- 04 PyTorch tutorial - How do computational graphs and autograd in PyTorch workwww.youtube.com
- PyTorch Tutorial 03 - Gradient Calculation With Autogradwww.youtube.com
- Automatic Differentiation with torch.autograddocs.pytorch.org
- PyTorch: Tensors and autograd — PyTorch Tutorials 2.13.0+cu130 documentationdocs.pytorch.org
Welcome back. Last lesson, you used indexing, reshaping, reductions, and broadcasting to turn tensors into the values you wanted. This time, you will use those operations to build a scalar objective and ask PyTorch for its derivatives.
In deep learning, an objective often measures how far a model’s predictions are from their targets. Autograd computes how that objective changes with respect to tensors we might eventually adjust, such as weights and biases. By the end of this lesson, you will be able to mark tensors for gradient tracking, call .backward() on a scalar objective, inspect the resulting gradients, and avoid carrying old gradients into a new calculation.
What autograd records
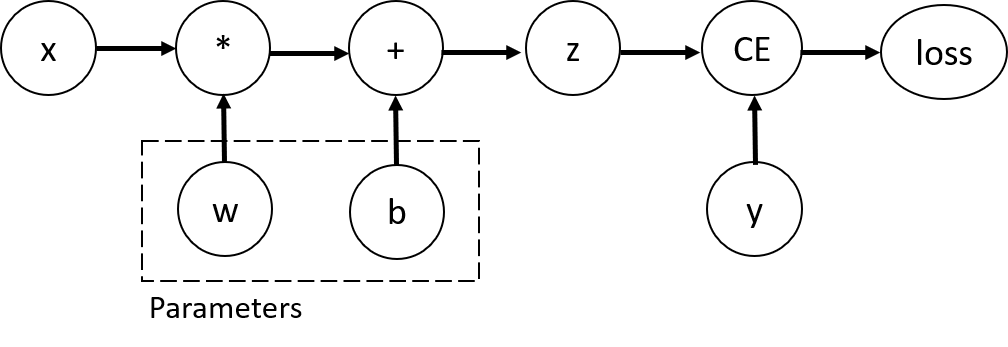
Suppose a prediction depends on an input , a weight , and a bias . PyTorch executes the tensor operations to produce a result. When a tensor such as has requires_grad=True, it also records the operations needed to differentiate a later objective with respect to .
The computational graph below shows this idea for a larger prediction: the input and parameters produce , which is compared with a target to produce a loss. The diagram shows the forward computation; autograd uses the recorded operations to calculate gradients backward from the loss.
Watch Patrick Loeber’s PyTorch Tutorial 03 - Gradient Calculation With Autograd for a short demonstration of the essential API.
PyTorch Tutorial 03 - Gradient Calculation With Autograd
Patrick Loeber’s tutorial shows how requires_grad=True lets PyTorch record operations and how .backward() computes a gradient.
Watch gradient tracking for the setup, then forward and backward for grad_fn, a scalar reduction, and .backward(). Focus on the distinction between the tensor whose value is computed and the leaf tensor whose .grad is filled.
For a more precise account, read the indicated parts of the official PyTorch tutorial. Its example uses a classification loss, but you do not need to understand that particular loss function yet; focus on which tensors require gradients and where gradients appear.
Automatic Differentiation with torch.autograd
Read PyTorch’s official explanation to connect the video’s commands to the computational graph and the chain rule.
Start with the code immediately before “Tensors, Functions and Computational graph,” identifying x, y, w, b, z, and loss. In that section, read from the paragraph beginning parameter tracking through the end of the paragraph explaining grad_fn. In “Computing Gradients,” read backward and leaves, including the code and note. Finally, in “More on Computational Graphs,” read forward versus backward. Stop before “Optional Reading: Tensor Gradients and Jacobian Products.”
A tensor you create directly with requires_grad=True is a leaf tensor. Operations involving it produce new tensors that carry a grad_fn describing how to continue the backward calculation. By default, .backward() accumulates gradients in the .grad attributes of the leaf tensors, not in the intermediate results.
Compute and check one gradient
Begin with one weight, a fixed input of , and a target of . Define the prediction as and the scalar objective as its squared error:
At , the prediction is and the objective is . Differentiating gives a check on what PyTorch should return:
At , that derivative is . In PyTorch:
import torch

w = torch.tensor(2.0, requires_grad=True)

prediction = 3 * w
loss = (prediction - 1).square()

print(loss)           # tensor(25., grad_fn=...)
print(loss.shape)     # torch.Size([])
print(w.grad)         # None: no backward pass yet

loss.backward()

print(w.grad)         # tensor(30.)
loss.shape is torch.Size([]): this is a zero-dimensional scalar tensor, like the result of the unrestricted mean() you saw last lesson. Calling loss.backward() on a scalar needs no additional argument. It computes derivatives through the recorded operations and stores the derivative with respect to w in w.grad.
Notice what the command did not do: it did not change w. A gradient reports how the objective would change locally if w changed; updating parameters is a separate step, covered later in this module.
Keep loss as a tensor until after .backward(). loss.item() is useful for printing its numerical value, but the resulting Python number has no autograd history on which to call .backward().
From several predictions to one objective
The previous example already produced a scalar. With a batch, calculations commonly produce one error per example first. A reduction such as .mean() turns those errors into one scalar objective.
Here are two examples with two features each. The matrix multiplication x @ w makes one prediction per row; broadcasting adds the scalar bias to both predictions.
x = torch.tensor([
    [1.0, 2.0],
    [3.0, 4.0],
])
target = torch.tensor([0.0, 2.0])

w = torch.tensor([1.0, -1.0], requires_grad=True)
b = torch.tensor(0.0, requires_grad=True)

prediction = x @ w + b
errors = prediction - target
loss = errors.square().mean()

print(prediction)       # tensor([-1., -1.], grad_fn=...)
print(errors)           # tensor([-1., -3.], grad_fn=...)
print(errors.shape)     # torch.Size([2])
print(loss)             # tensor(5., grad_fn=...)
print(loss.shape)       # torch.Size([])

loss.backward()

print(w.grad)           # tensor([-10., -14.])
print(b.grad)           # tensor(-4.)
Only w and b were marked with requires_grad=True, so those are the leaf tensors whose gradients we requested. The fixed inputs and targets do not need gradients for this calculation.
The mean matters to the values of the gradients, not just to the shape of loss. Here,
To check the bias gradient, increasing by a small amount increases both predictions by that amount. For a mean of two squared errors, its derivative is the sum of the two errors:
Each component of w.grad also collects a contribution from both examples, weighted by that example’s corresponding feature. This explains why w.grad has the same shape as w, even though loss is scalar. You will trace such contributions systematically with the chain rule later in the course; for now, being able to construct the objective and inspect its gradient is the goal.
A fresh calculation needs fresh gradients
There is one behavior to remember before using gradients in a training loop: .backward() adds to existing leaf gradients. It does not replace them. Return to the same video for the accumulation demonstration.
PyTorch Tutorial 03 - Gradient Calculation With Autograd
Return to the accumulation portion of Patrick Loeber’s tutorial to see why repeated backward passes require clearing old gradients.
Watch gradient accumulation. Concentrate on why the printed gradients grow across iterations and on the point at which the previous gradient is cleared. The optimizer shown near the end will be introduced in a later lesson.
This small example reproduces the behavior while recomputing the objective each time:
w = torch.tensor(2.0, requires_grad=True)

for _ in range(2):
    loss = (3 * w - 1).square()  # Build a fresh graph
    loss.backward()
    print(w.grad.item())        # First 30.0, then 60.0

w.grad = None                   # Clear the accumulated gradient

loss = (3 * w - 1).square()
loss.backward()
print(w.grad.item())            # 30.0 again
The objective and w stayed the same, so its derivative remained ; the second printed value was only because it included the earlier gradient. We rebuilt loss for each backward pass because a normal backward pass uses the recorded graph; to calculate again, run the forward operations again.
For this lesson, setting .grad = None is a simple way to clear a leaf tensor’s gradient. When you later use a PyTorch optimizer, you will normally clear gradients through that optimizer before calculating the next update. If you ever see an unexpected gradient, check both the scalar objective you reduced to and whether .grad still contains a contribution from an earlier calculation.
Conclusion
To differentiate a scalar objective with autograd, create the relevant leaf tensors with requires_grad=True, compute the objective using tensor operations, call loss.backward(), and inspect each leaf’s .grad. Reductions such as .mean() determine both the scalar objective and the scale of its gradients. Before a separate backward calculation, clear gradients that you do not intend to accumulate.
Next, you will package tensor computations into a multilayer perceptron using torch.nn.Module. The same autograd mechanism will track its parameters; the model class will give those parameters and computations a reusable structure.