Hello! Welcome back to our Docker course.
In our last lesson, you mastered techniques for analyzing and optimizing Docker images, using tools like docker history and Dive to create lean, efficient builds. We've focused on the static asset—the image. Now, we'll shift our attention to the dynamic, running instance—the container.
This lesson addresses the learning outcome: Monitor real-time container resource usage with docker stats. As a DevOps Engineer, you're constantly concerned with the performance and stability of running services. docker stats is your first-line diagnostic tool for understanding the resource footprint of your containerized applications in real time. It's the top command for the container world.
By the end of this lesson, you'll be able to use docker stats to monitor container performance, customize its output for scripting and automation, and understand the underlying kernel mechanisms that make this monitoring possible.
1. Basic Real-Time Monitoring
The simplest way to start is by running the command without any arguments. This gives you a live-streaming dashboard of all running containers.
docker stats
Let's watch a short video that introduces the command and its basic options.
Best Docker Container Monitoring Tools - Free and open source
This video from VirtualizationHowto provides a quick and clear introduction to the docker stats command, showing its basic usage and common flags.
Watch from 00:32 to 03:16. Pay attention to the live-streaming nature of the command and the description of flags like --no-stream (for a one-time snapshot) and --all (to include stopped containers).
The output you see will look something like this, showing key performance indicators for each container.
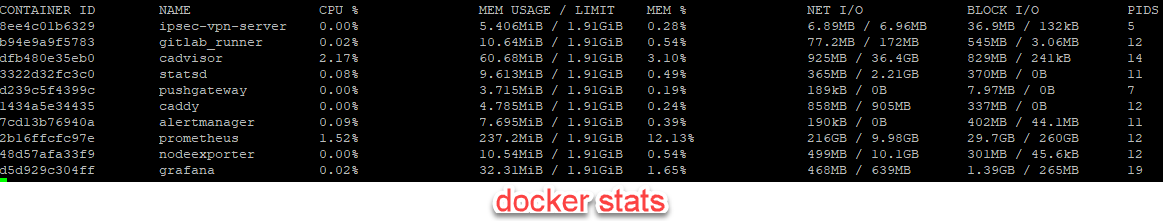
2. Understanding the Metrics
The default docker stats output provides a wealth of information. To use it effectively, you need to know what each column represents. Let's break them down.
Advanced Container Resource Monitoring with docker stats
The article 'Advanced Container Resource Monitoring with docker stats' by Last9 offers an excellent, detailed explanation of each metric. We'll use it to understand the columns in the output.
Read the section 'Breaking Down docker stats Output: What Each Metric Means'. Focus on understanding the nuances of each column: CPU %, MEM USAGE / LIMIT, MEM %, NET I/O, BLOCK I/O, and PIDS.
Here's a summary of the key points from the reading:
CONTAINER IDandNAME: Identifiers for the container.CPU %: The percentage of the host's total CPU capacity that the container is using. On a multi-core system, this value can exceed 100%. For example, 250% usage on an 8-core machine means the container is using 2.5 full CPU cores.MEM USAGE / LIMIT: The amount of memory the container is currently using, versus the total memory it's allowed to use. If no limit is set, the limit will be the host's total memory.MEM %: The container's memory usage as a percentage of its limit.NET I/O: The total amount of data received and transmitted by the container over its network interfaces.BLOCK I/O: The total amount of data read from and written to the host's block devices (i.e., disk I/O) by the container.PIDS: The number of processes running inside the container. A high number in a simple application could indicate a problem like a process leak.
3. Advanced Usage and Custom Formatting
While the default view is useful for a quick glance, in a professional DevOps context, you'll often need to script, automate, or integrate this data. This is where docker stats becomes particularly powerful.
You can customize the output using the --format flag, which uses Go template syntax. This allows you to select specific fields, format them, and even output them as JSON for easy parsing by other tools.
Advanced Container Resource Monitoring with docker stats
Let's return to the Last9 article to explore advanced formatting, which is key for automation.
Read the section 'Advanced Filtering and Custom Output Formatting for docker stats'. Pay close attention to the {{json .}} format for automation and the example that pipes this JSON to jq, a common tool in your field.
Practical Examples for Automation
-
Get a single snapshot of specific metrics in a table:
The--no-streamflag is essential for scripting, as it provides a one-time output instead of a continuous stream.# Show container name, CPU %, and Memory Usage in a clean table docker stats --no-stream --format "table {{.Name}}\t{{.CPUPerc}}\t{{.MemUsage}}" -
Output as JSON for scripting:
This is incredibly useful for feeding data into monitoring systems or scripts.# Get a JSON object for each running container docker stats --no-stream --format "{{json .}}"This will produce a raw stream of JSON objects, one per container.
-
Combine with
jqto find problematic containers:
Given your DevOps background, you'll appreciate how easily this integrates with command-line tools likejq.# Find all containers using more than 50% of their memory limit # The jq script filters the JSON objects based on the MemPerc field docker stats --no-stream --format "{{json .}}" | jq 'select((.MemPerc | rtrimstr("%") | tonumber) > 50)'
Test your understanding!
You are asked to write a command that produces a single, non-streaming, comma-separated value (CSV) output of all running containers. The report should include only the container's name, its CPU percentage, and its memory percentage, without any headers.
For example:my-web-app,0.54%,15.32%my-database,2.10%,45.80%
What command would you use?
Show answer
You would use the --no-stream flag for a single output and the --format flag to specify the fields and the comma separator.
docker stats --no-stream --format "{{.Name}},{{.CPUPerc}},{{.MemPerc}}"
4. Under the Hood: How It Works
docker stats isn't magic. It's a user-friendly frontend for metrics collected by the Linux kernel itself. Your background in Linux and Computer Science makes this an interesting area to explore.
Docker leverages a kernel feature called Control Groups (cgroups). Cgroups are responsible for isolating resources (CPU, memory, block I/O) for a collection of processes. As a side effect of managing these resources, the kernel exposes detailed metrics about them in a pseudo-filesystem, typically located at /sys/fs/cgroup.
The official Docker documentation provides an excellent overview of how runtime metrics are sourced from cgroups. This will give you a deeper appreciation for what's happening behind the scenes.
Read the section titled 'Control groups'. It explains that cgroups track processes and expose metrics, and shows you how to find where they are mounted on your system. You don't need to dive into the specifics of v1 vs v2 right now, just grasp the main concept.
In essence, when you run docker stats, the Docker daemon is reading files from directories like /sys/fs/cgroup/memory/docker/<container-id>/ and /sys/fs/cgroup/cpuacct/docker/<container-id>/, parsing the raw data, and presenting it in a human-readable format. This is why the command has very little performance overhead—it's just reading statistics that the kernel is already collecting.
Conclusion
In this lesson, you've learned how to use docker stats as a powerful tool for real-time monitoring of your containers. This moves your skills from managing static images to observing live, running applications—a critical competency for any DevOps role.
Key Takeaways:
docker statsprovides a live,top-like view of resource usage for all running containers.- The metrics include CPU, memory, network I/O, block I/O, and process counts, each with specific meanings.
- The
--formatflag is extremely powerful for automation, allowing you to create custom-formatted output, including JSON for easy parsing with tools likejq. - The underlying mechanism for this monitoring is the Linux kernel's
cgroupsfeature, which collects resource metrics with minimal overhead.
In our next lesson, we will build on this by looking at how to manage the container lifecycle. You will learn to manage the container lifecycle (stop, restart, remove) and configure restart policies for automatic recovery, ensuring your applications can gracefully handle failures.