In our last lesson, we explored Ridge and Lasso regularization, two powerful techniques for combating overfitting. We saw that Ridge (L2) excels at handling multicollinearity by shrinking coefficients of correlated features together, but it keeps all features in the model. In contrast, Lasso (L1) performs automatic feature selection by forcing some coefficients to exactly zero, but it can be unstable with correlated features, often picking one arbitrarily. This left us with a natural question: can we get the stability of Ridge and the feature selection property of Lasso in a single model?
This lesson introduces Elastic Net, the hybrid regularization method designed to do just that. We will examine how Elastic Net combines the L1 and L2 penalties and, most importantly, develop a clear framework for deciding when to use Ridge, Lasso, or Elastic Net in practice. This will give you a complete toolkit for regularized linear models, bridging the gap between theoretical understanding and practical application.
Elastic Net: The Best of Both Worlds
Elastic Net was created to address the limitations of Lasso, particularly its behavior with correlated features. The solution is elegantly simple: instead of choosing between the L1 and L2 penalties, Elastic Net includes both.
The cost function for Elastic Net is a direct combination of the Ridge and Lasso cost functions:
Here, we have two hyperparameters, and , which control the strength of the L1 and L2 penalties, respectively.
The "StatQuest with Josh Starmer" channel provides a concise and clear introduction to this idea.
Regularization Part 3: Elastic Net Regression
This short video explains how Elastic Net combines the Lasso and Ridge penalties into a single model.
Please watch from the beginning until the end of the hyperparameter explanation. Pay close attention to how the two lambda values allow the model to behave like ordinary least squares, Lasso, Ridge, or a hybrid of the two.
Practical Parameterization in Scikit-learn
While the formula with and is clear theoretically, scikit-learn uses a more practical parameterization that is easier to tune. Instead of two separate lambdas, it uses two different parameters:
alpha(): This is a constant that multiplies both penalty terms. It controls the overall strength of regularization. A largeralphameans stronger regularization.l1_ratio: This parameter controls the mix between the L1 and L2 penalties. It ranges from 0 to 1.- If
l1_ratio= 1, the penalty is pure L1 (Lasso). - If
l1_ratio= 0, the penalty is pure L2 (Ridge). - If
l1_ratiois between 0 and 1 (e.g., 0.5), it's a mix of both.
- If
The scikit-learn cost function is written as:
This might look complex, but the intuition is straightforward: alpha is the master "regularization knob," and l1_ratio is the "mixing dial" between Lasso and Ridge.
The following infographic provides an excellent summary of the problem Elastic Net solves and its structure.
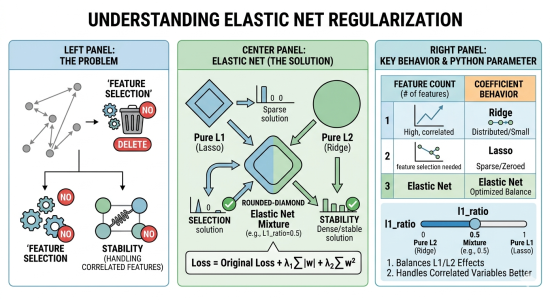
The Geometric View: A Rounded Diamond
In the previous lesson, we saw that the L2 constraint forms a circle and the L1 constraint forms a diamond. The shape of the Elastic Net constraint is a hybrid of these two, often described as a "rounded-diamond" or a "Stadium" shape.

This hybrid shape is key to its behavior:
- It still has corners, though they are softened. This means the error contours can still hit a corner, allowing coefficients to be set to zero and enabling feature selection.
- The edges are curved, not flat like the diamond. This curvature, inherited from the L2 penalty, is what helps stabilize the model when features are correlated.
The Grouping Effect: Elastic Net's Key Advantage
The most significant practical benefit of Elastic Net over Lasso is its handling of correlated features, known as the grouping effect.
Imagine you have a dataset with several highly correlated features, like sqft_living, sqft_above, and sqft_living15 in a housing dataset.
- Lasso, due to its sharp L1 constraint, will tend to arbitrarily select one of these features and assign it a non-zero coefficient, while forcing the others to zero. If you retrain the model on a slightly different subset of data, it might pick a different feature from the group. This makes the model unstable and less interpretable.
- Elastic Net, thanks to its L2 component, behaves differently. It encourages correlated features to be treated as a group. If one feature in the group is important, the model will tend to keep all features in that group, shrinking their coefficients together. It either keeps the whole group or removes the whole group.
This "grouping effect" results in more stable and often more realistic models, as correlated features frequently contain complementary information.
Let's return to the StatQuest video to see a visual explanation of this effect.
Regularization Part 3: Elastic Net Regression
This segment focuses specifically on how Elastic Net handles correlated parameters, which is its primary advantage over Lasso.
Watch from the start of the correlation explanation to the end of the video. The summary neatly contrasts Lasso's tendency to pick one feature with Elastic Net's ability to group them.
For a deeper textual explanation of this concept, we can refer back to the guide from "letsdatascience.com".
Regularization in Machine Learning: Ridge, Lasso, and Elasti
This article provides a clear explanation of why Elastic Net is superior to Lasso when dealing with correlated features.
First, read the section Elastic Net combines both penalties to understand Lasso's limitations and how Elastic Net's combined penalty offers a solution. Then, jump to the "Frequently Asked Questions" and read the answer to <span data-type="resource_reading_textrange" data-resource-subitem-id="14237736" data-range-start="What is the "grouping effect"" data-range-end="stable, informative model">the question about the "grouping effect". This reinforces why this behavior is so important in practice.
When to Use Each Method: A Decision Framework
You now have three powerful tools for linear regression: Ridge, Lasso, and Elastic Net. How do you choose the right one for a given problem? The choice depends on your data and your goals.
Here's a practical guide:
-
Start with Ridge Regression (L2) when:
- You believe most of your features are relevant to the prediction.
- Your primary concern is multicollinearity (high correlation between features).
- You prioritize model stability and are not concerned with creating a sparse model.
-
Use Lasso Regression (L1) when:
- You suspect many features are irrelevant and you want to perform automatic feature selection.
- You need a simple, interpretable model with a small number of non-zero coefficients.
- Your features are not highly correlated.
-
Use Elastic Net when:
- You have a large number of features, some of which are correlated (the grouping effect is highly beneficial here).
- You want the benefits of feature selection (like Lasso) but need more stability (like Ridge).
- You are working in a high-dimensional space where the number of features is greater than the number of samples . Lasso has a hard limit and cannot select more than features, whereas Elastic Net can.
In many ways, Elastic Net is the safest and most robust default choice. By tuning the l1_ratio, you can sweep the entire spectrum from a pure Ridge model to a pure Lasso model, and find the optimal balance for your specific problem using cross-validation.
The following resource provides an excellent summary table and a clear set of guidelines for making this decision.
Regularization in Machine Learning: Ridge, Lasso, and Elasti
This guide offers a structured way to decide which regularization method to use.
First, examine the table in the section When to use each method. This table provides a side-by-side comparison of the three methods on key criteria. Then, read the FAQ question How do you choose? for a concise, interview-style answer to this critical question.
To reinforce this, another helpful perspective is offered in the "Final Remarks" of the towardsdatascience.com article.
Lasso and Elastic Net Regressions, Explained: A Visual Guide with ...
This article provides a final narrative summary on selecting the right regression method.
Please read the section titled Final Remarks. It proposes a clear strategic workflow: start with Ridge or Lasso depending on your goals, and move to Elastic Net if neither provides satisfactory results.
Conclusion
In this lesson, we completed our tour of regularized linear models by introducing Elastic Net. You saw how it elegantly combines the L1 and L2 penalties to offer a robust and flexible solution that often outperforms Ridge or Lasso alone.
Key Takeaways:
- Elastic Net combines the L1 (Lasso) and L2 (Ridge) penalties to balance feature selection with stability.
- In
scikit-learn, it's controlled by two main hyperparameters:alphafor overall regularization strength andl1_ratiofor the mix between L1 and L2. - Its key advantage is the grouping effect, where it tends to keep or remove groups of correlated features together, leading to more stable models than Lasso.
- Elastic Net is often the best choice when you have many features, potential multicollinearity, and a need for feature selection. It serves as a powerful and safe default.
We have now covered the theory behind all three main types of regularized linear regression. In the next lesson, we will put this knowledge into practice. You will apply Ridge, Lasso, and Elastic Net to a real-world dataset using Python and scikit-learn, tune their hyperparameters, and directly observe their impact on model coefficients and predictive performance.