Welcome to the second module of our course, "Data Acquisition & Exploratory Analysis." In the previous module, you built a strong foundation in PyTorch, learning how to manage data, define models, and, most importantly, implement a complete training loop. Now that you have the engine, it's time to find the fuel: the data itself.
This lesson marks our first practical step into your project's data collection phase. Your goal is to gather text and images from various online sources, and we'll start with one of the richest: Reddit. Specifically, we will focus on using the Python Reddit API Wrapper (PRAW) library to programmatically scrape posts and their associated metadata from a target subreddit, like r/India. By the end of this lesson, you will have a working Python script to begin building the textual component of your dataset.
Why Use an API Wrapper like PRAW?
While you could try to scrape Reddit's website directly, this approach is brittle and often violates the platform's terms of service. A much more robust and respectful method is to use the official Reddit API. PRAW is a Python library that acts as a convenient wrapper around this API. It simplifies authentication, handles rate limits (how many requests you can make in a given time), and provides a clean, object-oriented way to access Reddit's data.
The GeeksforGeeks article below gives a great overview of PRAW and the steps we'll be following.
Scraping Reddit using Python - GeeksforGeeks
This article introduces the PRAW library and provides a clear guide on getting started. We will use it as our main reference for this lesson.
First, read the introductory section to understand what PRAW is. Then, follow the simple installation instruction under the Installation heading to install the library in your Conda environment.
Step 1: Authentication - Creating a Reddit App
Before you can access the Reddit API, you need to identify yourself as a developer and get a set of unique credentials. This involves creating a "script" application in your Reddit account settings. This process is standard for most APIs and is similar to how you might get keys for AWS services.
The credentials you need are:
client_id: A public identifier for your application.client_secret: A private key that should never be shared publicly.user_agent: A unique string that identifies your script, helping Reddit track API usage.
The following guide walks you through the app creation process step-by-step.
Scraping Reddit using Python - GeeksforGeeks
This section from the GeeksforGeeks article provides clear, illustrated instructions for creating a Reddit app and obtaining your API credentials.
Follow the instructions under the heading Creating a Reddit App. Make sure to select "script" as the application type. For the redirect uri field, you can use http://localhost:8080 as suggested. Once you create the app, carefully copy your client_id and client_secret.
After completing these steps, you will see a screen similar to the one below, displaying the credentials you need for your script.

This is an example of the Reddit application page where your client_id, client_secret, and user_agent name are displayed. Keep these credentials safe.
Step 2: Initializing the PRAW Client
With your credentials in hand, you can now write the script to connect to Reddit. This involves importing the praw library and creating a Reddit object, which will be your main gateway for all API requests.
For this project, you only need to read data, not post or comment, so we will use a read-only instance. This simplifies authentication as you don't need to provide your personal Reddit username and password in the script.
This video from Patrick Loeber provides a concise and clear demonstration of the entire setup process, from creating the app to initializing the PRAW client.
How To Scrape Reddit & Automatically Label Data For NLP Projects | Reddit API Tutorial
This video offers a great visual walkthrough of the authentication and initialization steps.
First, watch the segment on creating the app, which reinforces what you just read. Then, pay close attention to the section on setting up the client. Note how the client_id, client_secret, and a custom user_agent are used to create the praw.Reddit instance.
Here is the basic code structure for initializing your read-only PRAW client. Remember to replace the placeholder values with your actual credentials.
import praw

# It's a good practice to store credentials securely,
# but for this initial script, we'll place them directly.
# NEVER commit files with credentials to public Git repositories.

reddit = praw.Reddit(
    client_id="YOUR_CLIENT_ID",
    client_secret="YOUR_CLIENT_SECRET",
    user_agent="My Midday Meal Scraper v1.0 by u/YourUsername" # A descriptive user agent
)

print(reddit.read_only) # Should print True
Step 3: Scraping Posts from a Subreddit
Once your reddit object is initialized, you can start fetching data. The first step is to select a subreddit. For your project, this would likely be r/India.
subreddit = reddit.subreddit("india")
PRAW offers several methods to retrieve posts (submissions):
.hot(): Posts currently popular on the subreddit..new(): The most recently submitted posts..top(time_filter='all'): The all-time top posts. You can filter byyear,month,week,day, orhour.
However, for your project, the most powerful method will be .search(). This allows you to find posts that match a specific query, which is perfect for finding discussions related to "midday meal," "school lunch," or other relevant keywords.
The following resource explains how to use the search functionality.
Scraping Reddit with PRAW (Python Reddit API Wrapper)
This article provides a great example of performing a targeted search within a subreddit, which is exactly what you need for your project.
Focus on the sections explaining how to set search parameters and execute the search. Read from setting search parameters to see how a query, subreddit, and limit are defined. Then, look at the code under the iteration section to understand how to loop through the results. Note that the article uses .search() on a subreddit object, which is the key method for you.
Step 4: Extracting and Storing the Data
The .search() method returns a generator of Submission objects. Each Submission object is packed with useful attributes. For your project, the most relevant ones are:
submission.title: The title of the post.submission.selftext: The main body of a text post. This is crucial for capturing user complaints.submission.score: The post's net upvote count.submission.url: The permanent URL of the post.submission.created_utc: The creation timestamp, useful for temporal analysis.submission.num_comments: The number of comments, which can indicate the level of engagement.
The best way to handle this data is to iterate through the submissions, extract the fields you need into a dictionary, and then collect these dictionaries in a list. This list can then be easily converted into a Pandas DataFrame for analysis and storage.
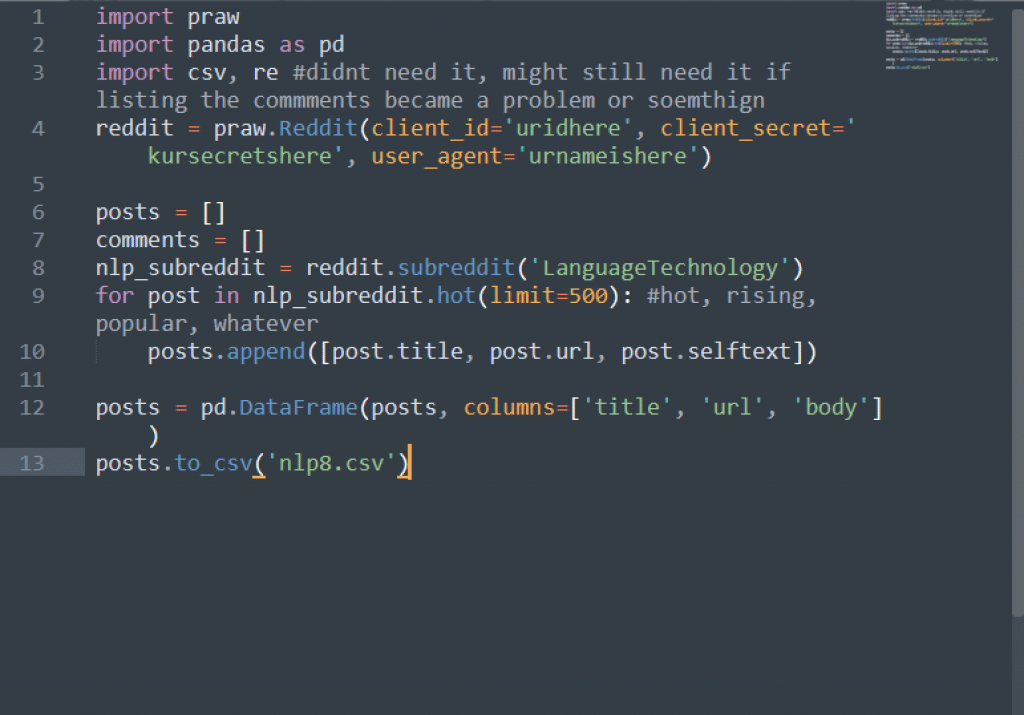
This code demonstrates the core logic: initializing PRAW, accessing a subreddit, looping through posts, and appending the desired data (title, URL, selftext) to a list before saving it.
Putting It All Together
Here is a complete script that you can adapt for your project. It searches the r/India subreddit for posts containing the phrase "midday meal," extracts relevant information, and saves it to a reddit_data.csv file.
import praw
import pandas as pd
from datetime import datetime

# --- 1. AUTHENTICATION ---
# Replace with your credentials.
# Consider using environment variables or a config file for better security.
reddit = praw.Reddit(
    client_id="YOUR_CLIENT_ID",
    client_secret="YOUR_CLIENT_SECRET",
    user_agent="Midday Meal Scraper v1.0"
)

# --- 2. SETUP ---
subreddit_name = "india"
search_query = "midday meal" # You can expand this with OR, e.g., '"midday meal" OR "school food"'
post_limit = 100 # Be mindful of API limits; start small.

subreddit = reddit.subreddit(subreddit_name)

print(f"Searching for '{search_query}' in r/{subreddit_name}...")

# --- 3. SCRAPING ---
scraped_data = []
for submission in subreddit.search(search_query, limit=post_limit):
    # Convert UTC timestamp to a readable datetime string
    post_time = datetime.utcfromtimestamp(submission.created_utc).strftime('%Y-%m-%d %H:%M:%S')

    scraped_data.append({
        'id': submission.id,
        'title': submission.title,
        'text_body': submission.selftext,
        'score': submission.score,
        'url': submission.url,
        'num_comments': submission.num_comments,
        'created_time': post_time
    })

print(f"Found and scraped {len(scraped_data)} posts.")

# --- 4. SAVING DATA ---
if scraped_data:
    df = pd.DataFrame(scraped_data)

    # Save to CSV
    output_filename = "reddit_midday_meal_data.csv"
    df.to_csv(output_filename, index=False)

    print(f"Data saved to {output_filename}")
else:
    print("No posts found for the given query.")
Run this script in your project directory. It will generate a CSV file containing the structured text data from Reddit, ready for the exploratory data analysis and model training phases of your project.
Conclusion
In this lesson, you have taken a significant first step in your project's data acquisition journey. You now have a repeatable, programmatic way to collect targeted textual data from Reddit.
Here are the key takeaways:
- PRAW is a powerful Python library for interacting with the Reddit API in a structured way.
- Accessing the API requires authentication via a
client_id,client_secret, anduser_agent, which you get by creating a 'script' app on Reddit. - The
.search()method is ideal for finding posts relevant to specific topics within a subreddit. - You can extract rich metadata from each post, including the title, body text, score, and creation time.
- Storing the scraped data in a Pandas DataFrame and saving it to a CSV file is an efficient workflow for data science projects.
You have now tackled your first data source. In the next lesson, we will address another common data collection scenario: scraping files and information from a public web portal. We will move from the structured world of APIs to the more unstructured web, using libraries like requests and BeautifulSoup to download images and documents.