Recommended resources
The freely available resources this lesson will direct you to.

Hello! Welcome to the final lesson in our module on architecting a Runtime Application Self-Protection (RASP) system.
In our previous lesson, we contrasted the architectures of WAFs and RASP, concluding that while RASP offers highly accurate, context-aware protection, its major operational challenge lies in its deployment model. Since a RASP agent is embedded within each application instance, managing a fleet of potentially thousands of these agents across a distributed environment becomes a critical system design problem.
This lesson tackles that challenge head-on. Our learning outcome is to: Design a centralized management console for configuring RASP policies and deploying them to a fleet of agents.
We will architect the system that brings order to this distributed fleet. Drawing on your background in software engineering and distributed systems, we'll approach this not as a simple configuration UI, but as a robust control plane designed for scale, security, and operability.
1. The Core Architectural Pattern: Control Plane and Data Plane
At its heart, a RASP management system is a classic example of a control plane/data plane architecture, a pattern you've likely encountered in networking, cloud services, and other distributed systems.
- The Control Plane: This is our centralized management console. Its job is to handle configuration, policy management, and administrative tasks. It's the "brain" of the system, making decisions but not handling the high-throughput application traffic itself.
- The Data Plane: This consists of the fleet of RASP agents running within your applications. Their job is to execute the policies defined by the control plane, inspecting application behavior and blocking attacks in real-time. They are the "hands" of the system, doing the actual security enforcement.
To solidify this foundational concept, let's watch a short video that explains this pattern using several analogies.
This video from IBM Technology provides an excellent first-principles explanation of the control plane and data plane architecture, highlighting the benefits of this separation.
Please watch the following sections: Introduction (00:00 - 00:47): Get a high-level overview of the concept. Database Service Example (00:47 - 04:49): Pay close attention to how administrative tasks (creating backups) are handled by the control plane, while data queries go to the data plane. This is analogous to our RASP console (policy changes) and agents (request inspection). Summary of Advantages (09:50 - 12:26): Focus on the discussion of security, independent scalability, and team organization. Think about how these apply to managing a RASP fleet.
As the video illustrates, separating the control and data planes allows us to scale and secure them independently. Our management console (control plane) may only serve a few administrators, while our RASP agents (data plane) might be running on thousands of application servers, handling millions of requests per second. This scale mismatch is the central challenge we must design for.
2. Designing the Policy Deployment Mechanism
How does the control plane securely and efficiently deliver policy and configuration updates to the vast, distributed data plane of RASP agents? A simple model where every agent polls the console's API can easily overwhelm the control plane, especially during system-wide startups or after a network partition heals—a phenomenon known as a "thundering herd."
We need a more resilient architecture. Let's explore several patterns used at scale.
Avoiding overload in distributed systems by putting the smaller service in control
This article from the Amazon Builders' Library is a masterclass in designing interactions between a small control plane and a large data plane. It discusses the exact problems we need to solve.
Please read the article, focusing on these key architectural patterns: 'Overload' section: Understand the risks of the simple data-plane-calls-control-plane (pull) model. 'Solving the problem of scale mismatch' section: Study the pattern where the control plane writes config to a scalable store like S3, and the data plane polls that store. This decouples the planes. 'Reverse the flow of API calls' section: Grasp the concept of the control plane pushing updates. Note the challenges it introduces, like inventory management. Final proposed architecture: Pay close attention to the elegant solution where the data plane agent establishes a long-lived connection, and the control plane takes over to push updates. This gives the control plane flow control without the complexity of inventory management.
Based on that reading, let's outline three viable architectures for our RASP policy deployment, moving from simple to more sophisticated designs.
Pattern 1: Decoupled Pull via an Intermediate Store
This pattern, described in the article using S3, adds a highly scalable buffer between the control and data planes.
- Architecture:
- An administrator publishes a policy change in the management console.
- The control plane compiles the new policy set into a versioned configuration file (e.g., a JSON or protobuf file).
- The control plane uploads this file to a highly available object store (like AWS S3, Google Cloud Storage, or a self-hosted MinIO).
- RASP agents periodically poll a well-known location in the object store for a new version file. If a new version is detected, they download and apply it.
- Trade-offs:
- Pros: Excellent scalability and resilience. The control plane is completely shielded from the agent fleet. If the control plane is down, agents can continue to function with their last-known good configuration and new agents can still fetch the latest policy. This property is called static stability.
- Cons: Higher propagation latency. Updates are not instantaneous and depend on the agents' polling interval. This may not be suitable for emergency "kill switch" scenarios.
Pattern 2: Push via Long-Lived Connections
This pattern gives the control plane the power to push updates in near real-time, which is ideal for dynamic environments.
- Architecture:
- When a RASP agent starts, it initiates a persistent, long-lived connection (e.g., a WebSocket or a gRPC streaming connection) to a load balancer in front of the control plane.
- The control plane maintains these connections. It doesn't need a persistent inventory of agents; its inventory is simply the set of active connections.
- When a policy is updated, the control plane iterates through its active connections and pushes the new configuration directly to each connected agent.
- Trade-offs:
- Pros: Very low latency for policy deployment. The control plane has direct control over the flow of updates.
- Cons: Higher state management complexity in the control plane (managing thousands of persistent connections). It also requires a more sophisticated communication protocol than simple REST/HTTP.
For a modern RASP system, the long-lived connection pattern (Pattern 2) is often preferred for its low latency, while the intermediate store pattern (Pattern 1) serves as an excellent fallback or can be used for less critical, bulk configuration data.
3. Secure Agent Registration and Communication
An agent can't just connect and start receiving policies. The control plane must trust the agent, and the agent must trust the control plane. This requires a secure registration or "bootstrapping" process.
A robust approach involves cryptographic identity and mutual TLS (mTLS).

Let's break down the flow shown in the diagram, adapting it for our RASP system:
- Provisioning: When a RASP agent is deployed, it's provisioned with a unique identity: a private key and a corresponding public key certificate issued by a trusted Certificate Authority (CA). The console is configured to trust this CA.
- Connection: The agent initiates a TLS connection to the management console's endpoint. Standard TLS ensures the agent is talking to the authentic console.
- Authentication:
- To prove its own identity, the agent creates a JSON Web Token (JWT) containing metadata (e.g., its unique ID, application name).
- It signs this JWT with its private key.
- The agent sends this signed JWT to the console over the established TLS connection (e.g., in a gRPC metadata header or an initial WebSocket message).
- Verification:
- The console receives the JWT. It retrieves the agent's public key from its own trusted store (or from the agent's certificate).
- It uses the public key to verify the JWT's signature.
- If the signature is valid, the console has cryptographically verified the agent's identity. The connection is now fully authenticated, and the console can begin sending policies.
This mTLS + JWT approach provides strong, two-way authentication, preventing rogue agents from connecting and stopping man-in-the-middle attacks.
4. Architecting the Management Console Backend
Now, let's design the internals of the control plane itself. It's more than just a UI; it's a collection of microservices responsible for managing the entire system.
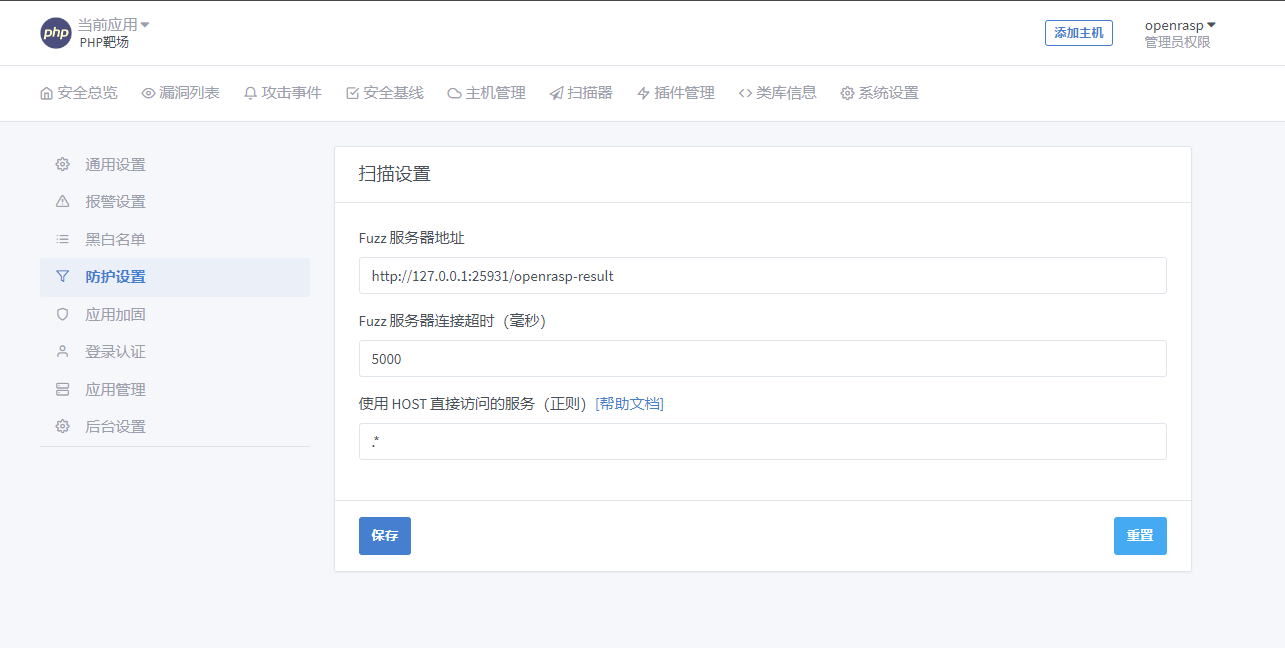
To power a UI like this, we need a robust backend. A critical best practice for managing policy is to treat policy as code.
Open Policy Agent: Best Practices for a Secure Deployment
This CNCF blog post, while focused on Open Policy Agent (OPA), outlines best practices for policy management that are directly applicable to our RASP console. It champions a GitOps-centric approach.
Please read these sections: 'Separate Policy Code from Application Code', 'Decouple Schema and Data', and 'Secure the Agent Itself': These reinforce the core principles of a clean policy architecture. 'Store Policy Code Securely Through GitOps' and 'Incorporate CI/CD and Branching Mechanisms': This is the key part. Understand how using Git as the source of truth for policies enables versioning, auditing, and safe, automated deployment.
Drawing from these principles, here is a high-level architecture for our management console:
-
Git Repository (The Source of Truth): All RASP policies are stored as text files (e.g., YAML, JSON, or a custom DSL) in a dedicated Git repository. This provides versioning, audit trails (via
git log), and a pull request workflow for peer review. -
CI/CD Pipeline: A CI/CD pipeline (e.g., GitHub Actions, Jenkins) is triggered on every commit to the main branch of the policy repository.
- Linting & Validation: The pipeline first validates the syntax and logic of the policy changes.
- Testing: It can run unit tests against the policies to prevent regressions.
- Deployment: On success, it signals the control plane that a new policy version is ready.
-
Control Plane Services:
- API Gateway: The single entry point for the UI and for agent connections.
- Policy Service: This service listens for signals from the CI/CD pipeline. When a new policy is approved, it pulls the latest version from Git, compiles it into the format needed by the agents, and stores it in a cache/DB. It then triggers the Agent Communication Service.
- Agent Communication Service: This service manages the long-lived connections to the RASP agents. When triggered by the Policy Service, it pushes the new policy set to all connected agents. It also receives heartbeats from agents.
- Agent Fleet Service: This service consumes heartbeat data to provide operators with a view of the fleet's health, including agent versions, running hosts, and policy statuses.
- Databases: A database (e.g., PostgreSQL) to store agent metadata, and a distributed cache (e.g., Redis) for session management and fast access to compiled policies.
This GitOps-driven architecture ensures that policy changes are managed with the same rigor and safety as application code changes.
Conclusion
In this lesson, we have designed a complete, scalable, and secure system for managing a distributed fleet of RASP agents. We moved from the core architectural pattern of control/data plane separation to specific, production-grade solutions for policy deployment and management.
Key Takeaways:
- Control/Data Plane Separation is the fundamental pattern for managing a distributed security system like RASP. The console is the control plane; the agents are the data plane.
- Policy Deployment at Scale requires moving beyond simple polling. Architectures using an intermediate store (like S3) for decoupling or long-lived connections for low-latency pushes are superior patterns.
- Zero Trust for Agents: Agents must be treated as untrusted until proven otherwise. A secure registration process using mTLS and signed JWTs provides strong, cryptographic authentication.
- Policy-as-Code using GitOps is the modern standard for managing security policies. It provides versioning, auditing, peer review, and automated, safe deployment.
This concludes our deep dive into architecting a RASP system. We have covered its internal instrumentation, its data export mechanisms, its relationship with WAFs, and finally, its centralized management.
Preview of the Next Module
Having focused intensely on protecting the application from within, we will now shift our perspective back to the network perimeter, but with a modern twist. The next module, Architecting Unified Edge Security Platforms, will explore how services like WAF, DDoS mitigation, and Bot Management are converging into integrated platforms at the network edge.