Hello! Welcome back to the course.
In our previous lessons, we've gone deep into the mechanics of building a blazingly fast Single-Producer, Single-Consumer (SPSC) lock-free queue. We've tackled data races, memory ordering, false sharing, and batching. You now have a powerful, reusable component.
However, a real-world telemetry system needs to capture data from many threads simultaneously. This raises a critical question: how do we adapt our SPSC queue, which is designed for one producer, to a multi-producer world? A naive approach might be to protect a single queue with a lock, but that would immediately create a performance bottleneck, re-introducing the very overhead we've worked so hard to eliminate.
This lesson bridges the gap between our single-queue component and a full-scale capture system. Our goal is to design a per-thread buffer architecture to eliminate write-side contention. We will architect a system that scales to dozens or even hundreds of threads without them ever waiting on each other, moving us one step closer to a truly zero-overhead profiler.
The Problem: The High Cost of Contention
Imagine you have a single, shared queue that all application threads write their log events to. Even if this queue is a highly-optimized, lock-free MPMC (Multi-Producer, Multi-Consumer) queue, the producers must still coordinate access to the queue's head pointer. This coordination, done via atomic operations, creates contention.
When multiple threads try to modify the same atomic variable at the same time, the CPU hardware ensures only one succeeds at a time. The others must retry or wait. This serialization torpedoes performance and scalability.
To understand just how expensive this is, let's consult the article 'A Concurrency Cost Hierarchy' by Travis Downs. It provides a brilliant mental model for the performance of concurrent operations.
Please read the following three sections: Level 2: Contended Atomics: This describes the performance cost when multiple threads fight over a single atomic variable or lock. This is the scenario we want to avoid. Pay attention to the benchmark results showing performance degrading as more threads are added. Level 1: Uncontended Atomics: This shows the cost of the same atomic operations, but when only a single thread is accessing them. Notice the significant performance jump. Level 0: Vanilla: This is the fastest level, achieved by avoiding atomic instructions altogether on the hot path. Focus on the tls_counter example, which uses thread-local storage to give each thread its own counter. This is a direct analogy for the architecture we are about to design.
The key takeaway from that article is that the cost of a concurrent operation depends heavily on the level of contention. Our goal for the telemetry system's "hot path"—the instrumented application threads—is to operate at Level 0. We cannot afford the performance penalty of Level 2 contention, as it would directly cause the "observer effect" we're trying to prevent.
The Solution: A Per-Thread Buffer Architecture
If multiple threads writing to one queue causes contention, the solution is simple but profound: give each thread its own queue.
This is the per-thread buffer architecture. Here’s how it works:
- One SPSC Queue Per Producer Thread: Instead of a single shared queue, every application thread that generates telemetry data gets its own dedicated SPSC ring buffer.
- Contention-Free Writes: A thread only ever writes to its own buffer. Since it's the sole producer for that buffer, there is no write-side contention. The write operation becomes an uncontended atomic update (Level 1) or, even better, a non-atomic write to thread-local data (Level 0).
- A Dedicated Consumer Thread: A single, background thread is created by the telemetry system. Its only job is to be the consumer. It periodically iterates through all the per-thread buffers, drains the data from each one, and consolidates it for processing and visualization.
This design elegantly partitions the problem. Each producer-buffer pair is a self-contained SPSC system, a problem we've already solved.
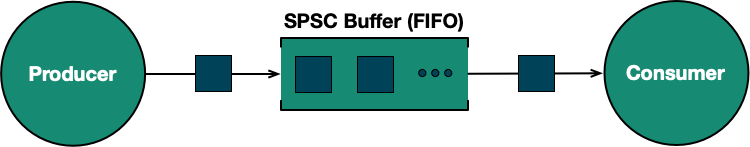
The critical insight here is that we move all the hard concurrent work to the cold path. The application threads on the hot path perform the simplest, fastest operation possible. The background consumer thread handles the complexity of polling multiple queues, but since it's not on the critical path, its performance is less of a concern.
A Real-World Example: The Quill Logging Library
This architecture isn't just theoretical; it's the backbone of many high-performance logging and telemetry systems.
Quill: High-Performance Asynchronous C++ Logging Library
The C++ logging library 'Quill' is a perfect example of this design in practice. Its documentation clearly explains how this architecture achieves high performance.
Read the sections 'Thread-Local Lock-Free Ring Buffer', 'Binary Log Message Serialization', and 'Asynchronous Backend Processing'. Notice how it explicitly names the core components of our design to achieve its performance goals.
Quill's design mirrors our goal precisely:
- Each application thread logs to its own thread-local SPSC queue.
- Writes are fast because they are contention-free.
- A dedicated backend thread asynchronously pulls data from these queues for formatting and output.
This validates our approach as a standard, industry-proven pattern for high-throughput data collection.
Test your understanding!
Imagine you are designing our telemetry profiler. You have two choices:
- MPMC Queue: A single, complex, lock-free MPMC queue shared by all threads.
- Per-Thread SPSC Queues: The architecture described in this lesson.
From a performance perspective, what are the primary trade-offs? Which is better for our profiler and why?
Show answer
-
MPMC Queue:
- Pro: Uses less memory (only one buffer). The consumer logic is simpler (only one queue to watch).
- Con: Suffers from write-side contention on the hot path. Even with lock-free atomics, threads will serialize when trying to claim a slot in the queue. The queue implementation is also significantly more complex than an SPSC queue.
-
Per-Thread SPSC Queues:
- Pro: Zero write-side contention on the hot path. Each thread writes to its own buffer without interfering with others, achieving Level 0/1 performance. The SPSC queue itself is a simpler data structure to implement and reason about.
- Con: Uses more memory (one buffer per thread). The consumer logic is more complex (it must discover and poll multiple queues).
Conclusion: For a telemetry profiler, minimizing overhead on the instrumented application threads (the hot path) is the absolute highest priority. Therefore, the per-thread SPSC architecture is the superior choice. It intentionally trades increased memory usage and consumer complexity for the fastest possible producer performance, effectively eliminating the observer effect.
Designing the System
With the core concept established, let's think about the practicalities of building this system.
- Buffer Management: How does the consumer thread know which buffers to poll? We'll need a central manager or registry. When an instrumented thread starts, it will create an SPSC buffer for itself and register a pointer to that buffer with the central manager.
- Thread Lifecycle: What happens when threads are created or destroyed?
- Creation: A mechanism is needed to ensure that the first time a thread emits a telemetry event, a buffer is created and registered. Thread-local storage is a natural fit for this.
- Destruction: When a thread exits, its buffer should be flushed by the consumer one last time and then either destroyed or marked for reuse. The manager needs to handle this deregistration safely.
- Consumer Logic: The consumer thread will run in a loop. In each iteration, it will get the list of active buffers from the manager and try to read from each one. If all buffers are empty, it should probably sleep for a short duration (e.g., a few microseconds or milliseconds) to avoid burning CPU cycles in a tight busy-wait loop.
This architecture provides incredible scalability on the write side, which is exactly what we need for a high-frequency event capture system.
Conclusion
In this lesson, we made a crucial architectural decision that will define our telemetry system. Instead of getting stuck on the problem of multi-producer contention, we sidestepped it entirely.
Key Takeaways:
- Contention is the enemy of scalability. Shared resources that are frequently written to by multiple threads create a performance bottleneck.
- The per-thread buffer architecture eliminates write-side contention by giving each producer thread its own private SPSC queue.
- This design moves all synchronization and consolidation work to a dedicated background consumer thread (the cold path), keeping the application threads (the hot path) as fast as possible.
- This pattern is a proven, industry-standard solution for high-performance logging and telemetry systems.
What's Next?
We've designed the blueprint for our capture system. The next logical step is to start building it. In the upcoming lesson, we will begin to translate this design into code. The learning outcome will be: "Implement a manager class to hold a collection of SPSC ring buffers, one for each instrumented thread." We will create the central component that discovers, stores, and provides access to all the per-thread queues for our consumer.