Introduction
In our last lesson, we unlocked the power of concurrent execution using CUDA streams. You learned how to pipeline work by breaking a problem into chunks and processing them in separate streams, allowing the GPU to overlap data transfers with kernel execution. This is a fundamental strategy for maximizing hardware utilization. However, simply launching work asynchronously isn't enough; to be effective performance engineers, we must be able to precisely measure the impact of our changes.
This brings us to the core of this lesson: CUDA events. While streams provide the "how" of concurrency, events provide the "how much." You will learn why host-side CPU timers are insufficient for profiling GPU code and how to use CUDA events to get accurate, low-overhead timing information directly from the device. We will then apply this new tool to quantify the performance benefits of the stream-based overlap we implemented previously, fulfilling a key part of the analysis-driven optimization cycle.
The Problem with Host-Side Timing
Your first instinct for timing code, likely informed by your C++ experience, might be to use a library like std::chrono. Let's consider what happens if you do this with a CUDA kernel:
auto start = std::chrono::high_resolution_clock::now();
my_kernel<<<grid, block>>>(...);
auto end = std::chrono::high_resolution_clock::now();
As we discussed, kernel launches are asynchronous with respect to the host. The call to my_kernel returns control to the CPU almost immediately, long before the kernel has finished executing on the GPU. The measurement you get from this code is merely the kernel launch overhead, which is typically just a few microseconds and is completely unrelated to the kernel's actual execution time.
A common first attempt to fix this is to force the CPU to wait for the GPU to finish before stopping the timer:
auto start = std::chrono::high_resolution_clock::now();
my_kernel<<<grid, block>>>(...);
cudaDeviceSynchronize(); // Block CPU until ALL GPU work is done
auto end = std::chrono::high_resolution_clock::now();
This is a significant improvement, as it now measures the true end-to-end time from launch to completion. However, it's still not ideal for precise kernel benchmarking. The cudaDeviceSynchronize() call introduces its own overhead from CPU-GPU communication. More importantly, it synchronizes the entire device, making it impossible to time a single operation within a complex, multi-stream pipeline without stalling everything.
For a detailed analysis of these timing methods, the following article provides excellent illustrations and data.
How to Benchmark CUDA Kernels - Guillesanbri
This blog post by Guillem Sanllorenç walks through the common pitfalls of benchmarking CUDA kernels and introduces events as the correct solution.
Please read the sections Asynchronous execution and CUDA Events. Pay close attention to the table comparing the timing results from cudaDeviceSynchronize with those from CUDA events—notice how the overhead is much more significant for shorter-running kernels.
CUDA Events: High-Precision GPU Timing
To solve the issues of host-side timing, CUDA provides the event API. An event is essentially a marker that you can place into a CUDA stream. When the GPU executes the operations in the stream, it records a high-precision timestamp as it passes the event marker. Because the timing is handled entirely on the GPU, it avoids the overhead and inaccuracy of synchronizing with the host.
The core API functions for timing are:
cudaEventCreate(cudaEvent_t* event): Creates an event object.cudaEventRecord(cudaEvent_t event, cudaStream_t stream = 0): Places the event marker into a specified stream. The0indicates the default stream.cudaEventSynchronize(cudaEvent_t event): Blocks the host CPU thread until the specified event has been recorded.cudaEventElapsedTime(float* ms, cudaEvent_t start, cudaEvent_t stop): Calculates the elapsed time in milliseconds between the recording of astartand astopevent. This function requires thestopevent to have completed, which is why it's typically preceded bycudaEventSynchronize(stop).cudaEventDestroy(cudaEvent_t event): Destroys an event object and frees its resources.
Here is the canonical pattern for timing a kernel:
// 1. Create event objects
cudaEvent_t start, stop;
cudaEventCreate(&start);
cudaEventCreate(&stop);

// 2. Record a "start" event in the stream before the work
cudaEventRecord(start, stream);

// 3. Launch the kernel(s) you want to measure
my_kernel<<<grid, block, 0, stream>>>(...);

// 4. Record a "stop" event in the stream after the work
cudaEventRecord(stop, stream);

// 5. Wait for the "stop" event to complete
cudaEventSynchronize(stop);

// 6. Calculate the elapsed time
float milliseconds = 0;
cudaEventElapsedTime(&milliseconds, start, stop);
printf("Kernel execution time: %f ms\n", milliseconds);

// 7. Clean up
cudaEventDestroy(start);
cudaEventDestroy(stop);
The article below provides a very clear summary of the event API and a concise example.
CUDA 01 — Streams & Events Walkthrough | Medium
This Medium post by YC Kuo gives a practical walkthrough of both streams and events with helpful diagrams and code.
First, review the API summary table in the section Core Event API. Then, study the code example in Timing with Events to see the API in action. Finally, look at the summary table in section When to Use What and the code snippet in Pattern 1 to solidify your understanding of the timing pattern.
Measuring the Effectiveness of Stream Overlap
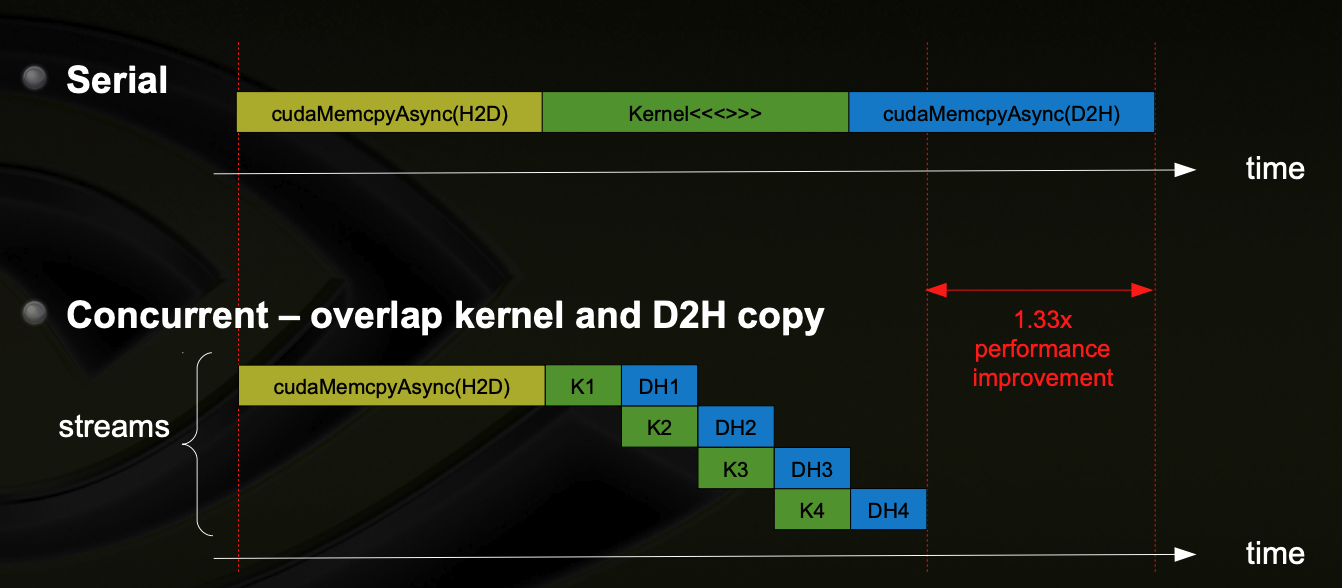
Now we can apply this precise timing tool to answer the question from our last lesson: how much faster is our pipelined execution? The strategy is straightforward:
- Benchmark the Serial Version: Use events to measure the total time taken for the sequence of
cudaMemcpy(H2D), kernel launch, andcudaMemcpy(D2H), all in the default stream. This is your baseline. - Benchmark the Concurrent Version: Use events to measure the total time for the pipelined version that uses multiple streams. You'll place the
startevent before you launch any of the streams' work and thestopevent after you synchronize all the streams. - Calculate Speedup: The speedup is simply
serial_time / concurrent_time.
The following resource contains a complete, self-contained code example that implements exactly this comparison. It's an excellent demonstration of putting everything together.
CUDA 01 — Streams & Events Walkthrough | Medium
This section of the same article provides a full demonstration of measuring the speedup from stream overlap.
Read and analyze the complete code example in section Measured Overlap Demo. Notice how it defines two functions, runSerial and runStreams, and then uses the cudaEvent timing pattern to benchmark both and compute the final speedup. This pattern is central to performance engineering in CUDA.
Events for Synchronization
Beyond timing, events are also the primary mechanism for creating explicit dependencies between streams. While operations within a stream are ordered, there is no default ordering between streams.
Imagine a producer-consumer scenario: streamA produces data that streamB needs to consume. We need to ensure streamB doesn't start its work until streamA is finished. cudaDeviceSynchronize() would work, but it's a sledgehammer that would stall all other independent streams too.
The precise solution is cudaStreamWaitEvent(cudaStream_t stream, cudaEvent_t event). This function is asynchronous; it tells a stream (streamB) to pause its execution until a specific event (event recorded in streamA) has been completed.
This fine-grained dependency management is crucial for building complex asynchronous pipelines.
Asynchrony and CUDA Streams | CUDA C++ Class Part 2
This video from NVIDIA Developer explains how to use streams to enable concurrency and how to resolve the data dependencies that can arise.
Watch from the introduction to streams to understand how different streams can execute concurrently. Then, focus on the section from the stream API to review the key functions. Finally, pay close attention to the example from using streams for overlap, which demonstrates how launching operations into different streams can create a data race, motivating the need for explicit synchronization like cudaStreamWaitEvent.
Conclusion
In this lesson, you've added a critical tool to your performance engineering toolkit. You now understand not only how to enable concurrent execution with streams but also how to accurately measure its impact with events. This ability to quantify performance changes is the bedrock of iterative optimization.
Key Takeaways:
- CUDA Events are the standard mechanism for high-precision, low-overhead timing of GPU operations.
- They are superior to host-side timers, which either measure the wrong thing (launch overhead) or introduce synchronization artifacts (
cudaDeviceSynchronize). - The
cudaEventRecordandcudaEventElapsedTimefunctions form the canonical pattern for benchmarking kernels and data transfers. - Events are essential for verifying and quantifying the speedup achieved through stream-based concurrency.
- Beyond timing, events enable fine-grained synchronization between streams using
cudaStreamWaitEvent, allowing you to build complex, safe, and efficient data pipelines.
With a solid grasp of asynchronous execution, measurement, and synchronization, you are now fully equipped to begin optimizing kernels in earnest. In our next module, we will dive deep into one of the most fundamental operations in AI: General Matrix Multiplication (GEMM). We will start with a naive implementation and methodically apply a series of advanced optimization techniques, using the profiling skills you've just learned to measure our progress at every step.