Hello! Welcome back to your course on Go.
In our last lesson, we made our API client more robust by using the context package to handle timeouts. This prevents our tools from hanging indefinitely when a service is unresponsive. However, a timeout simply tells us that an operation failed to complete in time; it doesn't distinguish between a permanent outage and a brief, transient network glitch.
For transient failures—like a temporary network hiccup, a server being momentarily overloaded, or a service restarting—simply failing is not the most resilient strategy. A better approach is to automatically retry the request. This lesson is dedicated to exactly that: we will implement client-side retry logic with exponential backoff for transient network errors.
You'll learn why a simple retry loop is dangerous, how exponential backoff and jitter solve this problem, and how to implement this pattern in Go using both a production-ready library and a custom, idiomatic approach.
1. Why Naive Retries Are Dangerous
Imagine a service you depend on goes down and then starts to recover. If your tool—and hundreds of others like it—immediately starts hammering the service with retries, you'll likely push it back over the edge, creating a "thundering herd" problem. Simple, fixed-delay retries can amplify failures rather than recover from them.
The solution is to wait for progressively longer periods between each retry. This is called exponential backoff.
Retries & Exponential Backoff - Deep Dive
To understand the problem and the solution visually, let's watch a deep dive into retries and exponential backoff. This video explains the concepts clearly, which is foundational for the code we'll write later.
Watch the following two segments: The Problem with Simple Retries (13:25 - 19:07): This part illustrates how a naive, fixed-delay retry mechanism can overload a recovering service. Introduction to Exponential Backoff (04:36 - 07:11): This short segment introduces the core problem and the need for timeouts, setting the stage for retries. Focus on why a simple retry loop is problematic and how increasing the delay between attempts helps.
As the video illustrates, a fixed-delay retry strategy can create destructive request spikes. By exponentially increasing the wait time, we give the downstream service a chance to recover.
2. The Power of Exponential Backoff and Jitter
The core idea of exponential backoff is to calculate the wait time using a formula like this:
wait_time = base_delay * (2 ^ attempt_number)
This creates a predictable, but still synchronized, pattern of retries. If many clients are using the same algorithm, their retries can still cluster together. To solve this, we introduce jitter, which adds a small amount of randomness to the backoff delay.
Retries & Exponential Backoff - Deep Dive
Let's continue with the same video to see how exponential backoff is calculated and why jitter is a crucial addition.
Watch these two segments: Calculating Exponential Backoff (19:07 - 23:02): This section walks through the backoff formula. Introducing Jitter (23:02 - 29:54): This part explains why even exponential backoff isn't enough at scale and how adding jitter (randomness) helps de-synchronize clients. Pay attention to how jitter smooths out the retry attempts over time.
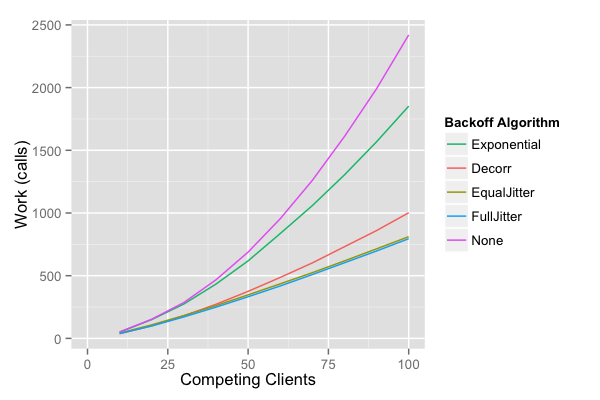
Adding jitter distributes the retry load, preventing clients from trying again at the exact same moments. The image below, from a classic AWS Architecture Blog post, shows this effect clearly. Notice how "FullJitter" and "EqualJitter" result in far fewer total calls (Work) as the number of clients increases, because they avoid contention.
3. Practical Implementation: Using a Library
For building DevOps tools, you often want a battle-tested, production-ready solution. HashiCorp, the creators of Terraform and Vault, provides an excellent library called go-retryablehttp that does exactly what we need. It's a pragmatic choice for getting robust retry logic into your applications quickly.
How to Implement Retry Logic in Go with Exponential Backoff
This article from OneUptime is a fantastic guide to implementing retry logic in Go. We'll focus on the section covering go-retryablehttp.
First, read the section titled "Using hashicorp/go-retryablehttp". Go through all its subsections: Basic Usage: See how simple it is to get started. Configuring Retry Behavior: Learn how to set max retries and min/max delays. Custom Retry Policy: This is critical. Pay close attention to the CheckRetry function, which lets you define which errors are retryable (e.g., 5xx server errors) and which are not (e.g., 4xx client errors). Custom Backoff Strategy: See how you can plug in your own backoff logic, including jitter.
Let's adapt our GitHub client from the previous lesson to use go-retryablehttp.
First, install the library:
go get github.com/hashicorp/go-retryablehttp
Now, let's modify the code. Notice how we replace the standard http.Client with retryablehttp.NewClient() and configure its retry policy.
package main

import (
	"context"
	"encoding/json"
	"errors"
	"fmt"
	"log"
	"net/http"
	"os"
	"time"

	"github.com/hashicorp/go-retryablehttp"
)

type GitHubUser struct {
	Login     string `json:"login"`
	Name      string `json:"name"`
	PublicRepos int    `json:"public_repos"`
}

// customRetryPolicy provides a check for retryable status codes.
// The default policy is good, but this shows how to customize it.
func customRetryPolicy(ctx context.Context, resp *http.Response, err error) (bool, error) {
	// First, check if the context has been cancelled.
	if ctx.Err() != nil {
		return false, ctx.Err()
	}

	// Retry on network errors or 5xx server errors.
	if err != nil {
		return true, err
	}

	// Retry on 429 Too Many Requests or any 5xx server error.
	if resp.StatusCode == http.StatusTooManyRequests || resp.StatusCode >= 500 {
		return true, nil
	}

	return false, nil
}

func main() {
	token := os.Getenv("GITHUB_TOKEN")
	if token == "" {
		fmt.Println("Error: GITHUB_TOKEN environment variable not set.")
		os.Exit(1)
	}

	// 1. Create a retryablehttp client.
	retryClient := retryablehttp.NewClient()

	// 2. Configure its behavior.
	retryClient.RetryMax = 3 // Max 3 retries
	retryClient.RetryWaitMin = 1 * time.Second // Min wait time
	retryClient.RetryWaitMax = 30 * time.Second // Max wait time
	retryClient.CheckRetry = customRetryPolicy // Our custom policy
	retryClient.Logger = log.Default() // Log retries for visibility

	// Get a standard client to use, which respects the context.
	// The overall timeout is still governed by the context.
	client := retryClient.StandardClient()

	// This overall timeout applies to the entire operation, including all retries.
	ctx, cancel := context.WithTimeout(context.Background(), 1 * time.Minute)
	defer cancel()

	req, err := http.NewRequestWithContext(ctx, "GET", "https://api.github.com/user", nil)
	if err != nil {
		log.Fatalf("Error creating request: %v", err)
	}

	req.Header.Set("Authorization", "Bearer "+token)
	req.Header.Set("User-Agent", "Go-DevOps-Tool/1.0")

	fmt.Println("Sending request...")
	resp, err := client.Do(req)

	if err != nil {
		log.Fatalf("Request failed after retries: %v", err)
	}
	defer resp.Body.Close()

	if resp.StatusCode != http.StatusOK {
		log.Fatalf("Error: received non-200 status code: %d", resp.StatusCode)
	}

	var user GitHubUser
	if err := json.NewDecoder(resp.Body).Decode(&user); err != nil {
		log.Fatalf("Error decoding JSON: %v", err)
	}

	fmt.Printf("Successfully fetched data for user: %s (%s)\n", user.Name, user.Login)
}
This approach is powerful because the library handles the complexity of exponential backoff, jitter, and respecting the request body for retries, letting you focus on the business logic.
4. Custom Implementation with http.RoundTripper
While libraries are great, understanding how to build retry logic from scratch is valuable. A very idiomatic Go pattern for this is to implement a custom http.RoundTripper.
An http.RoundTripper is an interface that represents the core of an HTTP transaction. You can think of it as a middleware for the http.Client. By creating our own RoundTripper, we can intercept an HTTP request, add logic (like retries), and then pass it on to the next RoundTripper in the chain (often the default one).
Go (Golang) http RoundTripper Explained
This video from Golang Cafe explains the http.RoundTripper interface and demonstrates how to build a custom RoundTripper for retrying requests. This is a great example of Go's composable design.
Watch these three segments: What is a RoundTripper? (02:01 - 07:20): Understand what the interface is and its potential use cases (logging, retrying, auth). Building a Retry RoundTripper (15:39 - 25:09): This is the core of the implementation. See how a for loop is used to wrap the Do call with retry and delay logic. Chaining RoundTrippers (28:27 - 31:24): Observe how elegantly the retry RoundTripper can be combined with a logging RoundTripper, showcasing composition.
This pattern is extremely powerful. It decouples the retry logic from the http.Client itself, allowing you to build a library of reusable, composable transport components. Your background in scripting and automation likely gives you an appreciation for creating such reusable building blocks.
Test your understanding!
You need to build an HTTP client that does three things for every request:
- Adds an
Authorizationheader. - Logs the request URL and the response status code.
- Retries requests that fail with a 5xx status code.
Using the http.RoundTripper pattern, how would you structure this? Describe the chain of RoundTripper implementations.
Show answer
You would create a chain of RoundTripper implementations, where each one wraps the next. The order is important. A typical flow would be:
Client -> AuthRoundTripper -> RetryRoundTripper -> LoggingRoundTripper -> DefaultTransport
AuthRoundTripper: This would be the outermost custom wrapper. ItsRoundTripmethod would add theAuthorizationheader to the request and then call theRoundTripmethod of theRetryRoundTripperit contains.RetryRoundTripper: This layer would implement the retry logic. It would call the innerLoggingRoundTripperin a loop. If a retry is needed, it waits and tries again.LoggingRoundTripper: This layer performs the actual request by calling theDefaultTransport. It logs the request before sending it and the response after receiving it.http.DefaultTransport: This is the final, built-inRoundTripperthat handles the actual network communication.
This demonstrates the power of composition in Go. Each piece of functionality is isolated in its own RoundTripper, and they can be assembled like LEGO bricks.
Conclusion
You have now learned how to build truly resilient HTTP clients in Go. Simply handling timeouts is good, but combining them with intelligent retry logic is what separates a basic script from a production-grade automation tool.
Key Takeaways:
- Naive retries can harm system stability; exponential backoff is the standard solution to give services time to recover.
- Jitter (randomness) should be added to backoff delays to prevent synchronized retries from multiple clients.
- Not all errors should be retried. Differentiate between transient errors (network issues, 5xx codes, 429) and permanent client errors (4xx codes).
- For a pragmatic, production-ready solution, use a library like
hashicorp/go-retryablehttp. - For custom logic and a deeper understanding of Go idioms, implement a custom
http.RoundTripper, which allows for powerful and composable client-side middleware. - Your retry logic must always respect the overall timeout set by the
context.Context.
Next Up
So far, we've built a robust and resilient client for interacting with an API. However, all our code is in the main package. To make it reusable for other tools, we need to structure it properly. In the next lesson, we will focus on how to structure a reusable API client package for a DevOps platform like GitHub or GitLab.